If you have ever stared at a Linux terminal and thought, “You know what this black rectangle needs? The entire internet,” congratulations: you are officially thinking like a power user. Browsing the web from a terminal is not just a nerd party trick. It is genuinely useful when you are working on a remote server, troubleshooting a site, downloading files over SSH, checking headers, reading documentation without opening a full browser, or just trying to feel dramatically more efficient than everyone else in the room.
The good news is that Linux gives you more than one way to browse the internet from the command line. You can use interactive text-based browsers like Lynx, w3m, Links, or ELinks if you want a browser-like experience. You can also use curl and wget when your goal is not “surfing” in the classic sense, but fetching pages, inspecting headers, following redirects, downloading files, or automating web tasks.
This tutorial walks through all of that in plain English, with practical examples and a few reality checks along the way. Because yes, you can browse from the terminal. No, it will not magically make every modern JavaScript-heavy website behave. And yes, it still feels very cool.
Why Browse the Internet from the Linux Terminal?
Terminal web browsing solves problems that a graphical browser cannot always solve elegantly. If you are connected to a remote server over SSH, there may be no desktop environment available. If you are troubleshooting redirects, headers, cookies, or downloads, a text-first approach is often faster than opening Chrome, clicking around, and pretending DevTools is your personality.
It is also great for low-resource environments. Text browsers use far fewer system resources than full desktop browsers. On older machines, minimal Linux setups, or server environments, that matters. And for automation, tools like curl and wget are the difference between “I checked one page” and “I built a script that checks 200 URLs before lunch.”
There is another benefit too: terminal browsing forces you to see what the web is actually sending back. Not the polished interface. Not the animations. Not the pop-ups begging you to accept cookies like a hostage negotiation. Just the response, the headers, the markup, and the data. For debugging, that is gold.
Choose the Right Tool for the Job
Interactive Text Browsers
If you want to move through links, open pages, read articles, and do light browsing directly inside the terminal, use an interactive text browser:
Lynx is the old-school legend. It is fast, lightweight, and perfect for reading text-heavy pages. w3m is a favorite because it can render tables nicely, works as both a browser and pager, and feels a bit more flexible. Links and ELinks add features such as better interface options, background downloads, color support, and in the case of ELinks, a more capable text-browser experience with tabbed browsing.
Non-Interactive Web Tools
If your goal is to fetch content, inspect headers, download files, save responses, test APIs, or automate tasks, use curl or wget.
curl is ideal when you want fine control over requests. It shines when working with headers, redirects, authentication, APIs, and custom request behavior. wget is fantastic for reliable file downloads, resuming interrupted transfers, recursive downloads, and creating local offline copies of websites. In short, curl feels like a surgical instrument, while wget feels like a dependable workhorse.
How to Install Terminal Browsing Tools on Linux
Many Linux systems already include curl and wget. Text browsers may need to be installed manually. Exact package names can vary slightly by distribution, but these examples usually work on mainstream systems:
After installation, confirm that a tool is available with:
If a command returns a path, you are ready. If it returns nothing, Linux is politely telling you that your next move should be package management.
How to Browse a Website Interactively from Terminal
1. Browse with Lynx
Lynx is one of the simplest ways to open a page from the terminal:
Once opened, use the keyboard to navigate links, move around the page, open help, and quit when you are done. Lynx is excellent for documentation, plain articles, and sites that are not obsessed with JavaScript frameworks.
Need plain output instead of interactive browsing? Lynx can dump a formatted page directly to standard output:
That is especially handy when you want readable text in a script, a log, or a terminal pipeline.
2. Browse with w3m
w3m is another excellent choice, and many Linux users prefer it for day-to-day terminal browsing:
w3m can render tables better than some older text browsers, which makes it useful for documentation pages, structured content, and directory browsing. It can also output rendered text, page source, or response headers without entering full interactive mode:
If you like the idea of “browser meets pager,” w3m is probably your terminal soulmate.
3. Browse with Links or ELinks
Links and ELinks are worth trying if you want a more feature-rich text browser:
Links offers a menu-driven interface and background downloading, while ELinks adds helpful features such as tabbed browsing. These tools are often more comfortable than they look at first glance. The interface may seem retro, but it gets the job done, and frankly, it has more personality than many modern websites.
How to Use curl to Browse and Inspect the Web
curl is not an interactive browser in the traditional sense, but it is one of the best tools for reading the web from a terminal. Think of it as browsing with intent.
Fetch a Page
This prints the server response to your terminal. For HTML pages, that means raw markup. It is perfect when you want to inspect content quickly or pipe it to another command.
Save the Output to a File
If you want curl to use the remote filename when appropriate, try:
Check Headers Only
This is one of the most useful terminal web tricks. A HEAD request lets you inspect response metadata without downloading the full body. Great for checking status codes, content type, content length, caching behavior, and whether a file has moved.
Follow Redirects
By default, curl does not automatically follow redirects. If a server returns a 3xx response, -L tells curl to chase the new location. This is essential when downloading moved files or testing final destinations.
Set a Custom User-Agent
Some servers behave differently depending on the User-Agent header. This can help when a site serves alternate content, blocks unknown clients, or you are testing how a request is identified.
Send Custom Headers
This is where curl becomes a superpower. You can inspect, test, and reproduce web requests from the terminal without opening a browser or an API client.
How to Use wget for Downloads and Offline Reading
If curl is the precision tool, wget is the dependable hauling machine. It is designed for non-interactive downloading and is excellent when you want to grab files, resume interrupted transfers, or mirror pages for offline use.
Download a File
wget will save the file in your current directory. Simple, direct, and satisfying.
Resume an Interrupted Download
The -c option continues a partial download rather than starting over. If your connection drops halfway through a giant file, wget does not throw a tantrum. It just picks up where it left off.
Save a Page for Offline Viewing
This is one of wget’s classic strengths. It can recursively download a website, convert links for local browsing, and fetch supporting assets such as stylesheets and images. It is useful for documentation archives, reference material, and local snapshots. Just be respectful of site policies, server load, and robots rules.
Download in the Background
This starts the download in the background and writes progress to a log file. Ideal when you want to kick off a long transfer and keep working.
What Works Well and What Does Not
Now for the honest part. Terminal browsing is wonderful, but it is not magic.
Text browsers work beautifully on documentation sites, technical guides, plain HTML pages, blogs with simple layouts, man pages, status pages, and internal dashboards that do not require heavy client-side logic. They are also excellent when you care more about the content than the visual design.
Things get messier on modern, heavily scripted websites. Many terminal browsers do not execute JavaScript the way desktop browsers do. CSS support is limited or ignored. Single-page apps, complex logins, drag-and-drop interfaces, pop-up authentication flows, and fancy interactive widgets may fail, partially render, or behave like they were assembled by a raccoon with a keyboard.
That is not a flaw so much as a mismatch. Terminal browsers are best when you want raw access, speed, clarity, and control. Use them for the right tasks and they feel brilliant. Use them for a deeply animated shopping site and they feel like a dare.
Best Practices for Terminal Web Browsing
Respect the Site
If you use wget recursively or script curl requests in loops, be mindful of server load, rate limits, and access policies. The fact that Linux lets you automate something does not mean you should impersonate an army of caffeinated robots.
Use HEAD Requests Before Large Downloads
When you are not sure what a URL points to, check the headers first:
This can save time, bandwidth, and regret.
Pipe Output Into Other Tools
One of the best parts of terminal browsing is how easily it combines with standard Linux tools:
That is where the command line really starts to shine. You are not just reading the web. You are processing it.
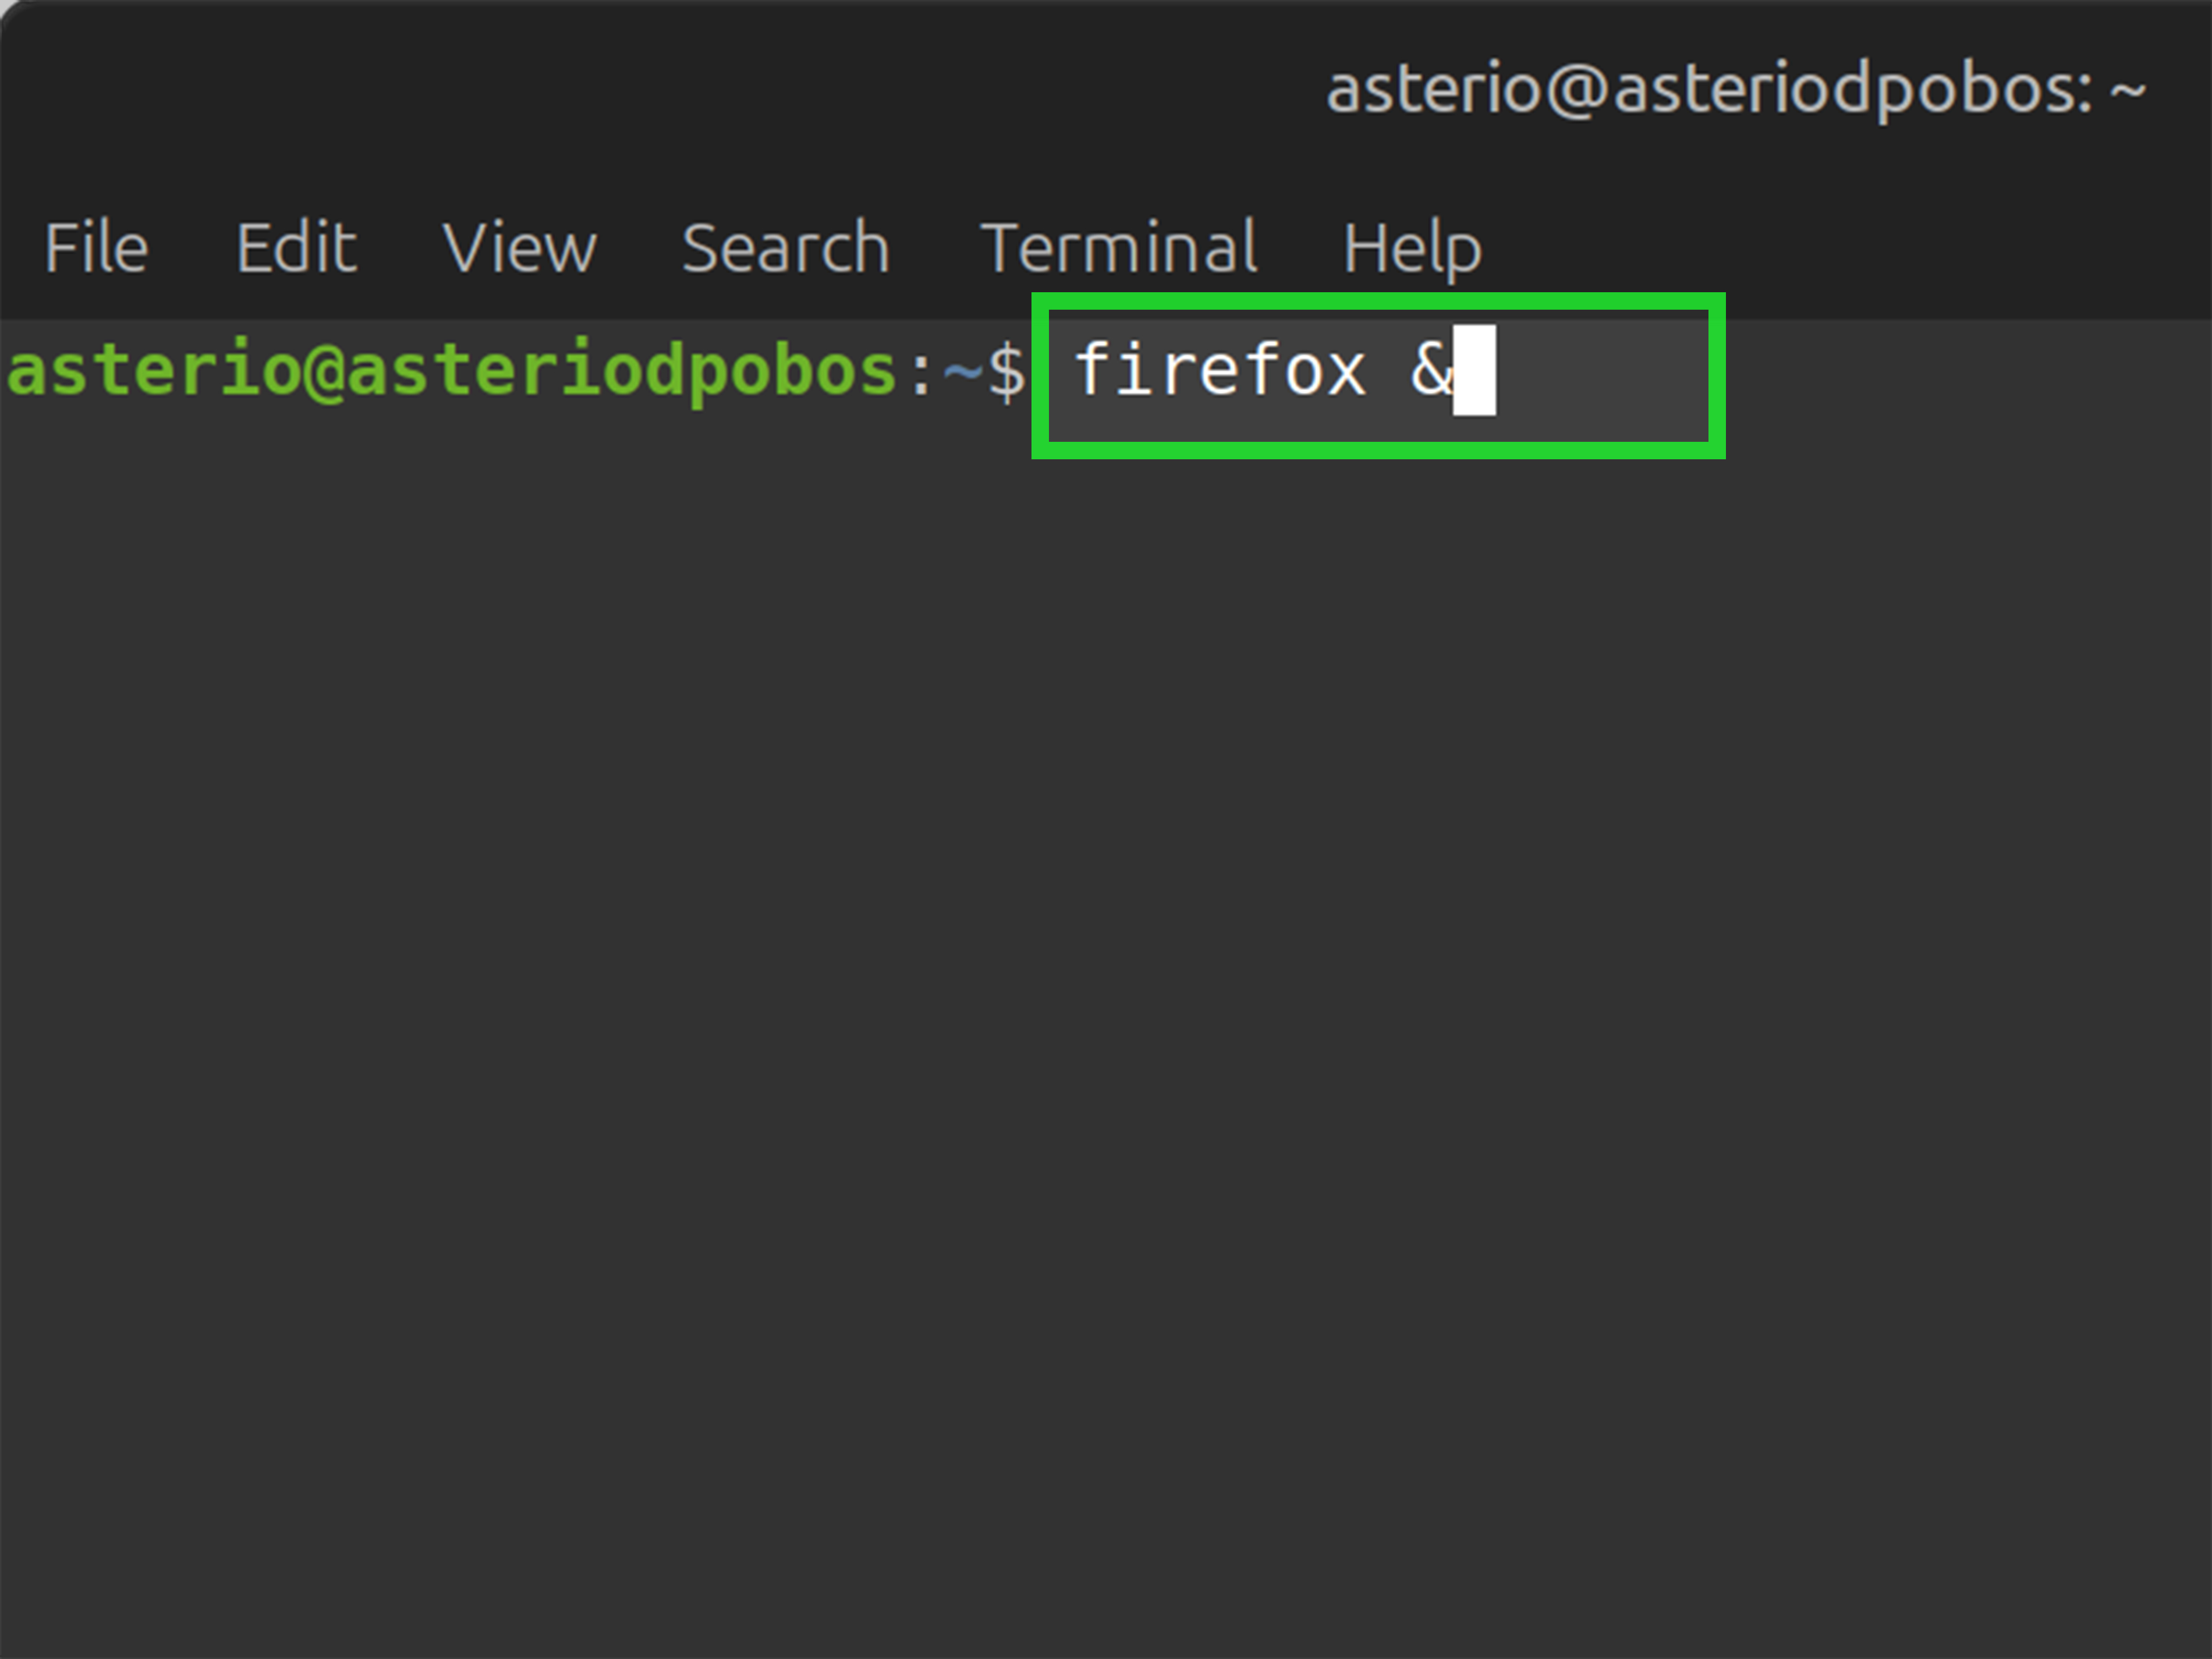
Know When to Switch Back to a GUI Browser
Sometimes the smartest terminal move is admitting that the site really wants Firefox or Chromium. That is not defeat. That is efficiency dressed as humility.
Troubleshooting Common Problems
Problem: The Page Looks Broken
That usually means the site depends heavily on JavaScript or advanced CSS. Try curl or wget to inspect the raw response, or open the page in a full browser if you need complete rendering.
Problem: curl Shows HTML Instead of Readable Text
That is normal. curl fetches the response body, not a rendered reading view. Pipe it into a pager, save it to a file, or use lynx -dump or w3m -dump for text output.
Problem: A Download Restarts From Zero
Use wget -c for resumable downloads, and make sure the remote server supports continuing the transfer.
Problem: A URL Redirects Somewhere Else
Use curl -I to inspect the redirect and curl -L to follow it. This is especially useful when a file has moved or a site rewrites old paths.
Experiences from Real Terminal-First Web Browsing
The most interesting thing about browsing the internet from a Linux terminal is how quickly it changes the way you think about the web. At first, it feels like a novelty. You open a page with Lynx or w3m, grin at the retro interface, and think, “Well, this is delightfully weird.” Then, after a few practical use cases, it stops feeling weird and starts feeling efficient.
One common experience is that terminal browsing makes you dramatically less patient with bloated websites. When you use a text browser, you see the bones of a page instead of the costume. If an article is readable, it remains readable. If a site depends on twelve layers of scripts just to display a button that says “Read more,” that becomes painfully obvious. It is a strangely refreshing reminder that content should still work as content.
Another real-world experience is how useful terminal browsing becomes on remote systems. Imagine you are logged into a cloud server over SSH, trying to verify a documentation page, follow a download link, or inspect an internal site. Launching a graphical browser is not even an option. In that environment, tools like curl, wget, and w3m do not feel old-fashioned. They feel like the correct tools. They are fast, they are scriptable, and they keep you inside the workflow you already have.
People also discover that terminal browsing sharpens their troubleshooting instincts. Instead of asking, “Why does this page look weird?” you start asking better questions: What status code did the server return? Is this a redirect? Which headers are present? Did the server send HTML, JSON, or a file? Is the issue in the content, the request, or the rendering layer? That shift is huge, especially for Linux users, sysadmins, developers, and anyone who touches web infrastructure regularly.
There is also a small but very real joy in the speed of it all. No waiting for tabs to wake up. No browser extension drama. No autoplay video ambush. No blinking ad trying to sell you a chair, a course, or a life philosophy. Just a terminal, a command, and the page or file you asked for. It feels direct in a way the modern web rarely does.
Of course, the experience is not universally magical. Some sites simply collapse outside a full browser. Logins can fail. Menus vanish. Interactive tools become unusable. That is normal. Terminal browsing is not here to replace Firefox. It is here to give you a smarter, lighter, more transparent option when the job fits. And when it does fit, it feels like you have discovered a secret side entrance to the internet.
Final Thoughts
If you want to browse the internet from a terminal in Linux, start with the simplest question: do you want to read and navigate, or do you want to fetch and inspect? For reading and navigating, use Lynx, w3m, Links, or ELinks. For fetching, downloading, redirect tracking, header inspection, and automation, use curl and wget.
That combination gives you a complete terminal web toolkit. It will not replace every graphical browser task, but it will absolutely make you faster, more flexible, and more comfortable working on Linux systems. Also, it makes you look like the kind of person who knows where the logs are before anyone else even opens Settings. That never hurts.
Note: This HTML includes only the <body> content for easy publishing, uses standard American English, and removes unnecessary artifacts for clean web output.